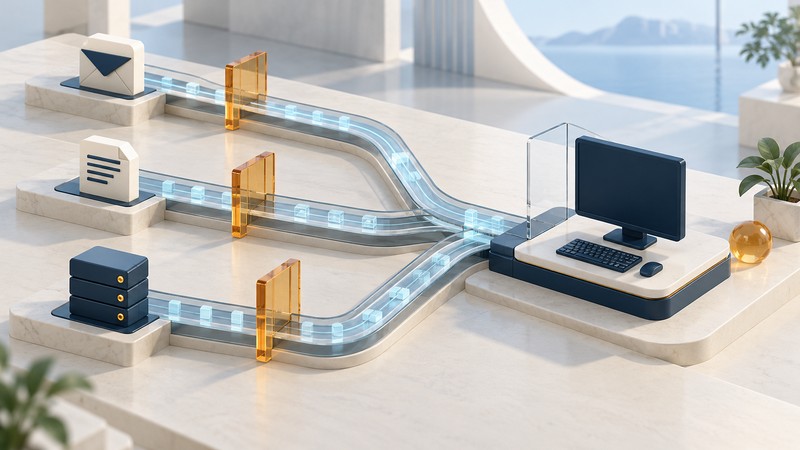
Nimda is a useful security case study because it crossed several boundaries at once: email, web browsing, vulnerable servers, shared folders and executable files. Understanding those connections explains why blocking one visible route could leave an organization exposed through another.
This retrospective describes the 2001 outbreak and draws out defensive lessons. It provides a way to reason about incidents, rather than a cleanup procedure for a present-day computer. For an active workplace incident, use your organization's response process and involve the people responsible for its systems.
Put the outbreak in its technical period
CERT/CC's September 18, 2001 advisory, preserved in the CERT mailing-list archive, described a worm spreading among Windows clients and IIS servers by several mechanisms. It reported disruption associated with scanning and mail propagation. Read this as contemporary incident evidence: early advisories can be revised as investigators learn more.
One relevant vulnerability had already been documented in Microsoft bulletin MS01-020 on March 29, 2001. A MIME-handling flaw in affected Internet Explorer versions could cause an attachment to execute while an HTML message was rendered. That history matters because it links exposure to software behavior and patch state, beyond a user's decision to open a conventional attachment.
Microsoft's later Nimda family analysis describes file infection, propagation through shares and backdoors, and changes that could weaken local access controls. Keep dates, variants and affected versions attached to such claims. A historical filename by itself is insufficient to identify an infection today.
Follow the connections, not just the first symptom
Mail and web content
Hostile content → vulnerable handling on a client → another infected endpoint.
Shared files
Infected endpoint → writable shared content → another user's application or workstation.
Server exposure
Compromised endpoint → vulnerable or already-compromised server → altered web content.
Feedback into the network
New infected host → additional traffic and reachable systems → more opportunities to spread.
This is a conceptual map of the historical routes, not a sequence that every infection followed. Its point is that a workstation could be both a victim and a source of further exposure. The same boundary should be examined in both directions: what can enter this host, and what can it change elsewhere?
The original CERT advisory separately identified mail, open shares, compromised websites, IIS directory traversal and backdoors left by earlier worms. A single “email virus” label would hide much of that picture.
Give each boundary a control and a check
On a narrow screen, scroll the table horizontally. Keyboard users can focus the table region and use the arrow keys.
| Boundary | Control to examine | Evidence to seek |
|---|---|---|
| Content entering a client | Maintained mail, browser and endpoint protections. | Versions, update state and handling of a harmless test case. |
| One host reaching another | Purposeful network segmentation and permitted connections. | Documented required paths and tested restrictions. |
| Users writing shared content | Permissions matched to actual work. | A normal account can change only its intended resources. |
| Internet-facing services | Asset ownership, maintenance and exposure review. | A complete service inventory and verified patch decisions. |
| Return to operation | Recovery plan and trusted restoration material. | Integrity and business-function checks before reconnection. |
These are questions for a current environment, not claims that today's products reproduce a 2001 configuration. The useful lesson is to assign each control an owner, a scope and a test. A dashboard that reports one component healthy leaves the other boundaries to be assessed.
Worked exercise: the mail filter is only one checkpoint
Run this discussion with a paper diagram and fictional records. Give each observation a time and source. Ask participants to distinguish confirmed facts from hypotheses, and to state what evidence would change their next decision. The goal is coordination and clearer reasoning; malware samples are unnecessary.
A useful outcome is a short action record: observation, affected service, responsible person, containment decision, evidence retained, recovery test and unresolved question. That record makes gaps visible without requiring a technical demonstration of the worm.
Recovery needs its own acceptance criteria
Containment limits further harm. Remediation addresses the causes and unwanted changes. Recovery restores a service to an agreed operational state. Keep those outcomes distinct when deciding whether an incident is over.
NIST SP 800-61 Revision 3, published in April 2025, places incident response within broader risk management. Its recovery guidance calls for checking restoration material, validating restored assets and confirming normal operation with system owners. That is a more useful finish line than disappearance of a single alert.
For a real environment, record which systems were assessed, what was restored, which credentials or permissions needed attention, what business tests passed, and who accepted the return to service. Review the findings afterward so missing ownership or untested backups become concrete maintenance work.
Nimda's lasting lesson is the connection between systems. Good protection and recovery plans follow those connections from an initial observation through to a verified result.